Read news on llama.cpp with our app.
Read more in the app
Llama.cpp on a jailbroken PS5: run any GGUF model natively on the console
AMD ROCm vs. Vulkan Performance For Lemonade Local AI Server With Llama.cpp
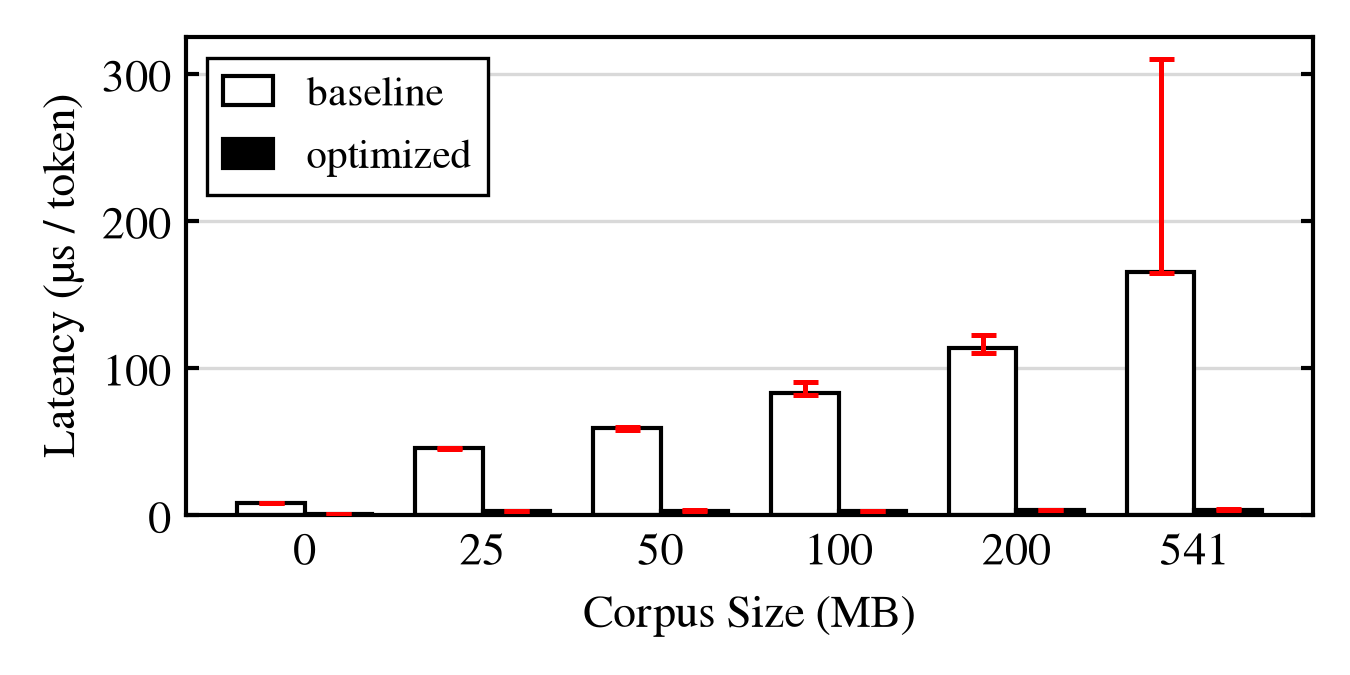
Faster prompt lookup drafting in llama.cpp
Llama.cpp v0.1.0
Apple Silicon and macOS VMs: Faster LLM Inference with llama.cpp
Building a Rust Inference Engine That Matches Llama.cpp
Intel Releases OpenVINO 2026.1 With Backend For Llama.cpp, New Hardware Support
Dell Pro Max GB10 vs. AMD Ryzen AI Max+ Framework Desktop For Llama.cpp, OpenCL & Vulkan Compute
Intel Arc B580 vs. AMD Radeon RX 9000 vs. NVIDIA RTX 50 Series For Llama.cpp Vulkan Performance
AMD ROCm 7.1 vs. RADV Vulkan For Llama.cpp With The Radeon AI PRO R9700
Valve Developer Contributes Major Improvement To RADV Vulkan For Llama.cpp AI
Tinker with LLMs in the privacy of your own home using Llama.cpp
Mistral Integration Improved in Llama.cpp
Vision Now Available in Llama.cpp
Heap-overflowing Llama.cpp to RCE
Llama.cpp AI Performance with the GeForce RTX 5090 Review
Llama.cpp supports Vulkan. why doesn't Ollama?
Llama.cpp Now Supports Qwen2-VL (Vision Language Model)
Llama.cpp guide – Running LLMs locally on any hardware, from scratch
Go library for in-process vector search and embeddings with llama.cpp