Read news on Qwen with our app.
Read more in the app
Run Qwen 3.8 Flash Next (125B) on consumer hardware (RTX 4090) at 100T/s
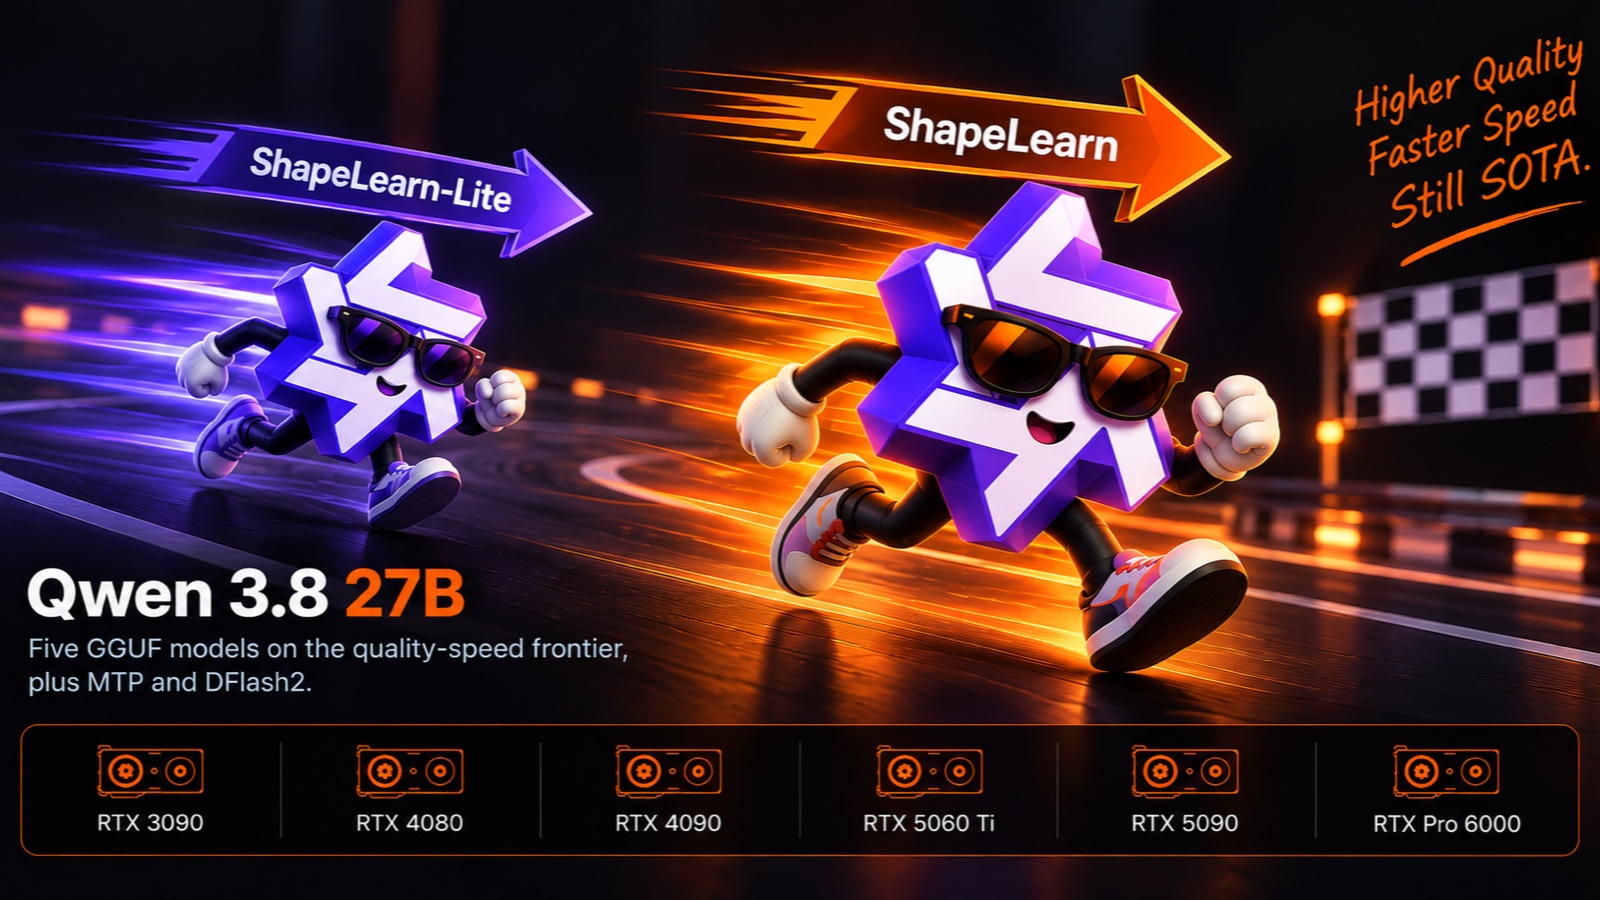
Shapelearn Qwen 3.8 27B (13.1 GB VRAM)
Benchmarking Qwen 3.8 27B on RTX 5090 and beyond — VRAM capacity alone can't overcome severe software and inference engine bottlenecks
Qwen 3.8 27B Uncensored – Testing the Uncensored Qwen Model
Alibaba Releases Smaller, Cost-Effective Qwen AI Model
Show HN: I made a Raspberry with Qwen my local car AI
I gave Qwen 3.8 27B a reverse-engineering job and it finished in 30 minutes
Why China's DeepSeek, Qwen and Moonshot Are a Worry for US AI Rivals
Alibaba’s open-source AI model Qwen overtakes Meta, Google to claim top spot globally: report
Qwen3.8-2.4T
Apple Briefly Posts China Guide for Connecting Siri to Qwen AI
Kimi K3, Qwen 3.8, and Anthropic's (Potential) Unravelling
Qwen 3.8 Max Preview
Apple Intelligence approved for launch in China with Alibaba’s Qwen AI
RTX 5080 and RTX 3090 Setup: 80 Tok/s on Qwen 3.6 27B Q8
Nvidia's new open weights Nemotron 3 super combines three different architectures to beat gpt-oss and Qwen in throughput
Something is afoot in the land of Qwen
Alibaba’s Qwen tech lead steps down after major AI push
Show HN: On-device browser agent (Qwen) running locally in Chrome
Bypassing Gemma and Qwen safety with raw strings