Read news on inference with our app.
Read more in the app
Qwen Image 2.1
A search-and-inference database from scratch in pure Zig
Benchmarking Qwen 3.8 27B on RTX 5090 and beyond — VRAM capacity alone can't overcome severe software and inference engine bottlenecks
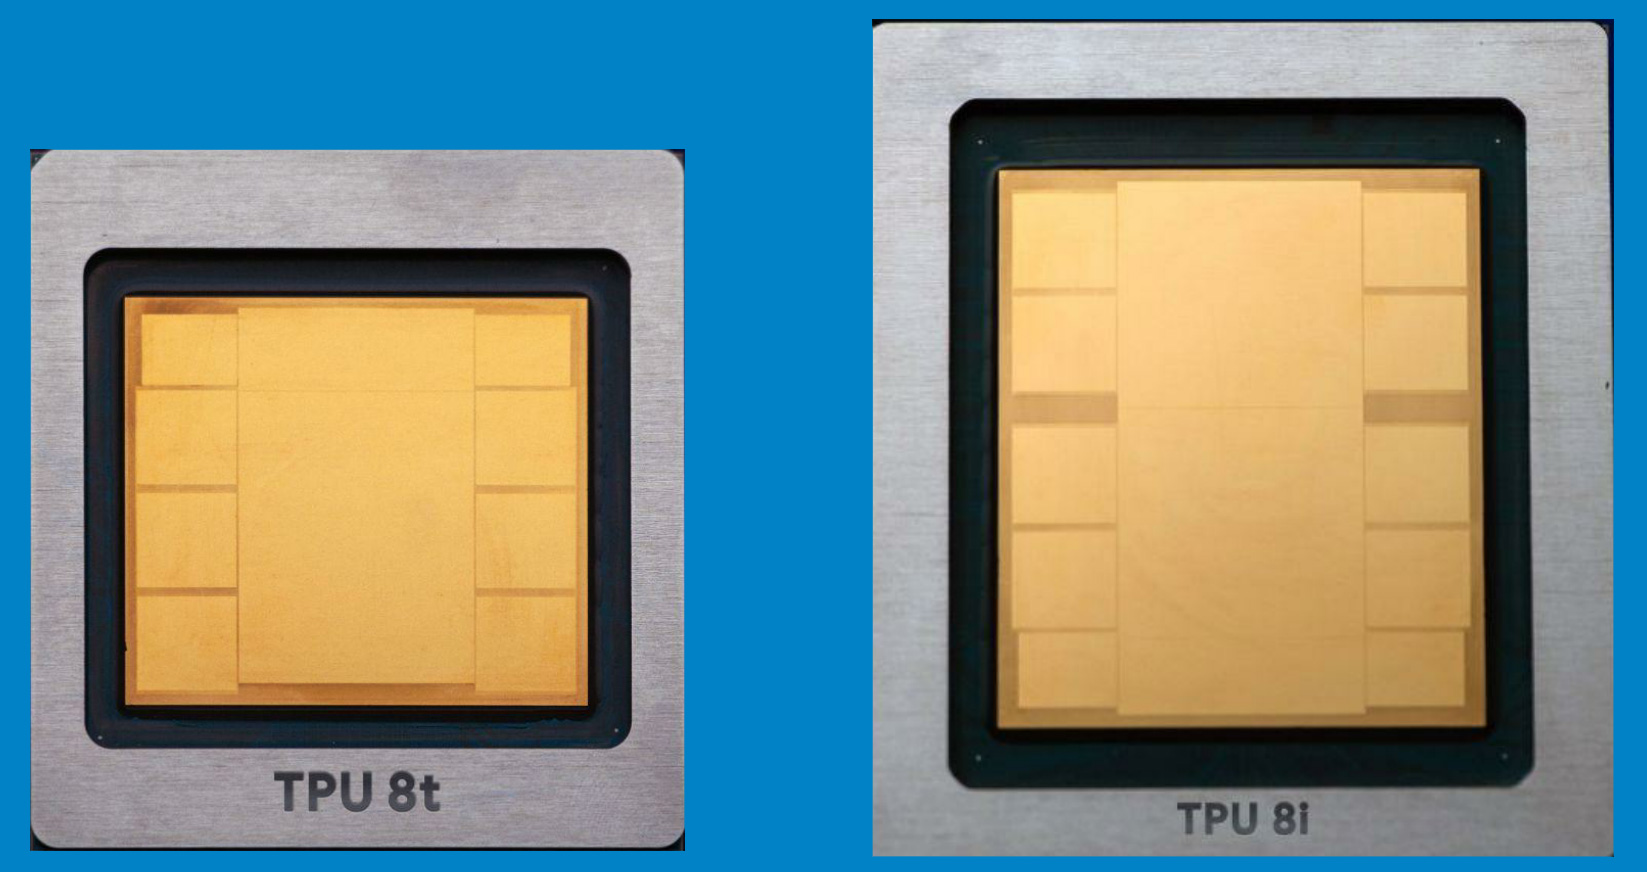
Google’s TPUv8s for Training and Inference at Hot Chips 2026
Kog is going deeper to squeeze more inference out of GPUs
MacPaw taps Liquid AI to offer on-device inference to devs building for its app store
Codex starts encrypting sub-agent prompts
AMD ZenDNN 6.0 Brings Many Improvements For Accelerating Inference On Ryzen/EPYC CPUs
Hot French startup ZML releases free product to speed inference across lots of AI chips
Inference cost at scale with napkin math
KV Cache Is Becoming the Memory Hierarchy of Inference
Inference is giving AI chip startups a second chance to make their mark
Train-to-Test scaling explained: How to optimize your end-to-end AI compute budget for inference
Google Gemma 4 Runs Natively on iPhone with Full Offline AI Inference
Your developers are already running AI locally: Why on-device inference is the CISO’s new blind spot
The team behind continuous batching says your idle GPUs should be running inference, not sitting dark
Launch HN: RunAnywhere (YC W26) – Faster AI Inference on Apple Silicon
Pure C, CPU-only inference with Mistral Voxtral Realtime 4B speech to text model
TTT-Discover optimizes GPU kernels 2x faster than human experts — by training during inference
Inference startup Inferact lands $150M to commercialize vLLM